
Until recently, websites were optimized for two types of visitors: people and search engine crawlers. Today, there is a third one — the AI agent.
An AI agent can browse a website on a user’s behalf, search for information, compare products, fill out an order form, or collect data to answer a question.
There are now several tools that can help prepare a website for this new type of interaction:
- llms.txt gives agents a structured overview of the website, while Markdown provides clean, machine-readable versions of individual pages
- WebMCP describes the actions available on the site
- ai-catalog.json helps agents discover connected AI services
Google Chrome is actively developing WebMCP, Lighthouse has introduced a dedicated Agentic Browsing category, and PageSpeed Insights can already display it alongside Performance, Accessibility, Best Practices, and SEO.
Let’s look at what these technologies do and where each of them fits.
llms.txt: a site map for AI agents
An AI agent can browse a website in much the same way a human does: open the homepage, follow the navigation, enter the catalog, find shipping and return information, and open individual product pages.
The problem is that this requires multiple requests and consumes model context and tokens, even though the website owner already knows which pages are actually important.
llms.txt collects these entry points in one simple file. An agent can start there and immediately understand what the project is, which sections matter, and where useful information can be found.
On Maison Plush, a fashion website we recently optimized for AI search, the site includes a clothing catalog, collections, brand pages, contact information, legal documents, and Instagram.
For a human visitor, all of this is already available through the site navigation. For an AI agent, the same structure can be described in a dedicated text file:
https://maison-plush.com/llms.txt
Its contents might look like this:
# Maison Plush

Paris fashion brand and online boutique.

## Shop

- [Fashion](https://maison-plush.com/fashion)
- [Collections](https://maison-plush.com/collections)

## Products

- [Vinyl Jacket and Skirt](https://maison-plush.com/fashion/vinyl-jacket-and-skirt)
- [Black Set](https://maison-plush.com/fashion/black-set)
- [Khaki Set](https://maison-plush.com/fashion/khaki-set)
- [Wool Set](https://maison-plush.com/fashion/wool-set)

## Maison Plush

- [About](https://maison-plush.com/about)
- [Contact](https://maison-plush.com/contact)

## Information

- [Terms](https://maison-plush.com/terms)
- [Privacy](https://maison-plush.com/privacy)
- [Cookie Policy](https://maison-plush.com/cookie-policy)
- [Disclaimer](https://maison-plush.com/disclaimer)

## Social

- [Instagram](https://www.instagram.com/plush.maison)
With a single lightweight Markdown file, an agent can immediately understand that Maison Plush is a fashion store, that products live under /fashion, collections under /collections, and that brand information and purchasing policies have their own dedicated pages.
The llms.txt file acts as the map. Detailed information still lives on the website itself.
For example, an agent may discover the Fashion section through llms.txt, open a particular product page, and then retrieve the price, sizes, availability, and description from there.
You can also reference llms.txt from every page on the website:
<link rel="describedby" href="/llms.txt">
This means that even if a browser agent lands directly on a product page from an external source, it can discover the website’s main AI-oriented map from the document <head>.
Markdown Product pages give agents a cleaner product view
Markdown is a lightweight text format with very little presentation overhead. It is easy to read both for humans and AI systems, while still allowing information to be structured clearly.
Suppose the normal product URL is:
/products/wool-set
You can provide a lightweight alternative alongside it:
/products/wool-set.md
The HTML page can advertise the existence of that version through its <head>:
<link rel="alternate" type="text/markdown" href="/products/builder-gel-nude.md">
This Markdown discovery mechanism was introduced in llms.txt v2 and is intended to provide machine-readable alternatives to regular web pages.
A product document might look like this:
# Wool Set > Maison Plush Paris product information. 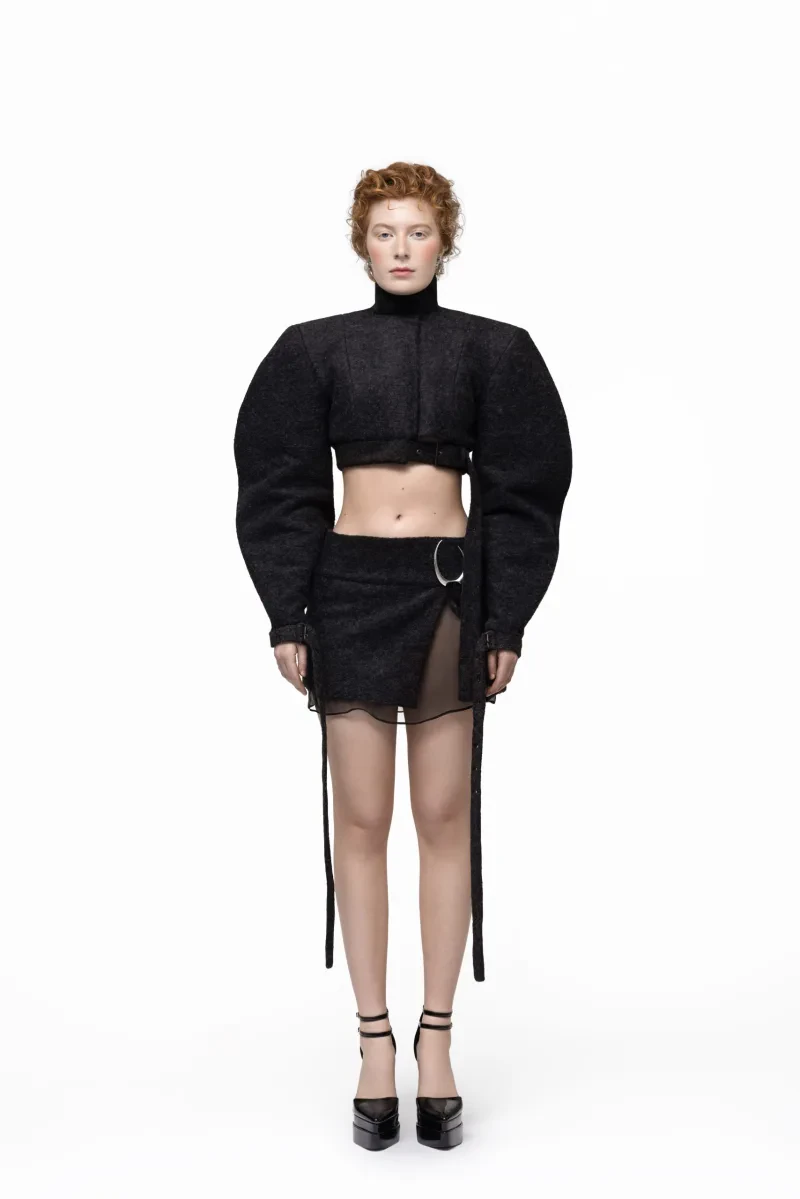 - Product URL: https://maison-plush.com/fashion/wool-set - Collection: Luna Code 26 - Purchase status: Available ## Pre-order This item is available for pre-order. A pre-order request can be submitted from the product page. ## Description A sculptural wool set shaped through precise construction and controlled volume. The silhouette is defined by tailored balloon sleeves with internal boning, allowing them to hold their shape while moving with measured fluidity. A silk underskirt introduces contrast — lightness against structure. A custom metal element, hand-sculpted in wax, cast in bronze using jewelry techniques, and finished with rhodium plating, adds a precise point of tension. The shape shifts with the body, expanding and narrowing with movement.
On the HTML page, the same information may be scattered across a heading, size selector, marketing copy, JavaScript components, and various interface elements.
In Markdown, the key data can be collected into one compact document.
For an online store, this version is best generated dynamically. That way, price, inventory, and pre-order status stay synchronized between the HTML and Markdown versions.
The idea behind a Markdown Product page is simple: it is a Markdown representation of a product page, structured in a way that is easy for AI agents to consume.
The regular product page can then use rel="alternate" to tell agents that this machine-friendly version exists.
It is still worth keeping the familiar Schema.org Product and Offer structured data for traditional search engines such as Google. AI agents can read that data too, although agent-oriented interfaces may prefer other formats.
WebMCP describes what an agent can do on your website
WebMCP allows a website to tell AI agents, browser agents, voice assistants, and other automated systems which actions are available.
Imagine a user asks:
Find a professional nail lamination gel under €20 and add two units to my cart.
Without a dedicated interface, the AI agent has to locate the search field, enter a query, figure out whether filters exist and how they work, open products one by one, select the correct variant, and click the relevant buttons.
With WebMCP, an online store can expose explicit tools such as:
searchProducts
getProduct
addToCart
checkDelivery
searchProducts might accept parameters such as:
query
category
maxPrice
availability
And addToCart could accept:
productId
variantId
quantity
The agent gets structured functions it can call to find the correct product and potentially start the purchasing process.
For service businesses, the same concept could allow an agent to book a consultation on behalf of its user or reserve a hotel room.
Google introduced WebMCP as a way for websites to expose structured tools directly to AI and browser-based agents while still operating inside a normal website.
Since June 2026, WebMCP has been available through an Origin Trial in Chrome 149. Chrome can already expose and execute these website tools through DevTools.
For an online store, it makes sense to begin with one genuinely useful action, such as product search.
Shopping cart operations, delivery calculations, and checkout actions can be added later. E-commerce platforms are already beginning to experiment with these kinds of agent-friendly interactions.
ai-catalog.json
The name can be slightly misleading: ai-catalog.json is a catalog of AI resources, not a catalog of products.
The file can be placed at:
/.well-known/ai-catalog.json
It allows a website to list available MCP servers, A2A agents, AI skills, datasets, and other machine-oriented services.
The AI Catalog specification is currently in draft status.
For example, a company may expose its own MCP service for working with a product catalog:
{
  "specVersion": "1.0",
  "entries": [
    {
      "identifier": "urn:air:example.com:mcp:shop",
      "displayName": "Shop MCP",
      "type": "application/mcp-server-card+json",
      "url": "https://example.com/mcp/server-card"
    }
  ]
}
An AI agent that already knows the example.com domain could check:
/.well-known/ai-catalog.json
and automatically discover the MCP service.
The specification also proposes declaring the catalog in the page <head>:
<link
  rel="ai-catalog"
  href="/.well-known/ai-catalog.json"
  type="application/ai-catalog+json"
>
For a typical online store with a standard HTML product catalog, this file provides relatively little value on its own.
It becomes much more useful once the website exposes its own MCP server, AI agent, skill, dataset, or another dedicated AI interface.
PageSpeed Insights is already beginning to reflect these changes
In May 2026, Lighthouse added an Agentic Browsing category designed to evaluate whether websites are technically prepared for AI agents.
In PageSpeed Insights, several core checks can now be related to this area, including the accessibility tree, interface stability measured through CLS, and llms.txt.
WebMCP is part of a broader set of Lighthouse experiments and currently depends on experimental Chrome capabilities.
That is also a good indication of where the technology stands today: the ecosystem is already becoming practical, but some parts are still actively evolving.
Conclusion
We are already implementing technologies that make our clients’ websites easier for emerging AI search systems and autonomous agents to discover, understand, and interact with.
The value of adopting these technologies early is straightforward: when new discovery channels appear, websites that are already structured for them are easier to find and easier for AI systems to use.
That can provide an early advantage while competitors are still adapting — and in digital markets, early visibility often compounds over time.
Mark Vi
Tech UI/UX Expert with over 15 years of experience
